
Not a data factory
The data work that gets your model from “it mostly works” to production-ready.
AI teams ship new model versions every couple of weeks. Data pipelines don't move that fast — especially once they're outsourced to people without the ML background to make the calls that matter. We stay a step ahead, so the data's ready before you need it.
- We understand ML, not just labeling
- Outsourced data work usually breaks down because whoever's doing it can't make the calls that need ML judgment — what to prioritize, which edge cases matter, when a schema's wrong. That's the actual job.
- AI-assisted, on purpose
- We use AI tools ourselves to annotate faster. We're not precious about doing everything by hand — just about the quality bar at the end.
- A step ahead, not behind
- Data teams are usually scrambling to catch up once a retrain is due. We track your roadmap and aim to already be ready.
Built for the teams shipping the next generation of models
What we do
Data work across the whole pipeline
We run every stage ourselves — the same small team from the first call to the last delivery.
Data collection
Sourcing net-new data to spec — field capture, licensed content, participant recruitment, and structured web collection with provenance you can audit.
Annotation & labeling
Bounding boxes, segmentation, transcription, RLHF preference data, classification, and custom schemas — done by people who understand why the schema is shaped that way, and AI-assisted tooling where it makes us faster.
Off-the-shelf datasets
Pre-built, licensed datasets you can start training on this week — with documented collection methods and known limitations.
Benchmarks & evals
Held-out test sets and task suites that actually discriminate between models, with human baselines and a rubric your team can defend.
QA & data audits
We grade an existing dataset for label noise, bias, leakage, and coverage gaps, then hand you a remediation plan.
Human-in-the-loop ops
Ongoing review queues, red-teaming, and adjudication for models already in production.
Data types we work with
Every modality a model can learn from
If a model can train on it, we can collect and label it.
Images & video
Detection, segmentation, keypoints, tracking, captioning
Text & language
NER, intent, summarization pairs, instruction data, translation
Audio & speech
Transcription, diarization, emotion, wake-word, far-field capture
Documents
OCR, layout, table extraction, key-value pairs
Sensor & geospatial
LiDAR, point clouds, IMU, GPS traces, satellite
Multimodal
Vision-language pairs, grounded QA, agent trajectories
Benchmarks & evals
Benchmarks that hold up
A benchmark is only useful if it separates a good model from a great one — and if you can explain every label in it.
Contamination-checked
We screen against common pretraining corpora so your eval isn't measuring memorization.
Human baselines included
Every task ships with expert human performance and inter-annotator agreement, so model scores have a reference point.
Versioned & documented
Datasheets, per-item difficulty, and a changelog. Reproducible runs, not a moving target.
Private hold-outs
Optional sealed test splits we score for you, so the answer key never leaks.
Process
How an engagement works
Scope
A call to pin down the task, edge cases, volume, and quality bar. You get a spec and a fixed quote.
Pilot
A small paid batch — usually 3–5 days — so you can check label quality against your own rubric before committing.
Production
We scale up with layered QA — annotator, reviewer, automated checks — and lean on AI-assisted tooling ourselves to keep pace with how fast you're iterating, without dropping the quality bar.
Delivery & iteration
Data ships in your format with a datasheet. We run your model's error analysis, find the edge cases it's still missing, and go collect exactly that — usually before you've had to ask.
Why Datatation
Why teams work with us
The right expert for the task
Radiologists for medical imaging, native speakers for language, drivers for AV scenarios — people who understand the task, not just the labeling tool.
Traceable, licensable data
Every item traces back to its source and consent basis — licensing you can defend in a diligence review.
Quality checked either way
Gold sets, blind re-labeling, and agreement metrics on every delivery — whether a person or an AI-assisted tool did the first pass.
Ahead of your retrain cycle
Most data operations lag the AI team, scrambling to source data after a model's already stalled. We track your roadmap and aim to have the next batch of edge cases ready before the retrain is due.
Founders
Run by people who've actually done this work
Not career labeling-ops people who picked up AI as a buzzword — one of us trains LLMs for a living, the other has shipped production ML systems for seven years.
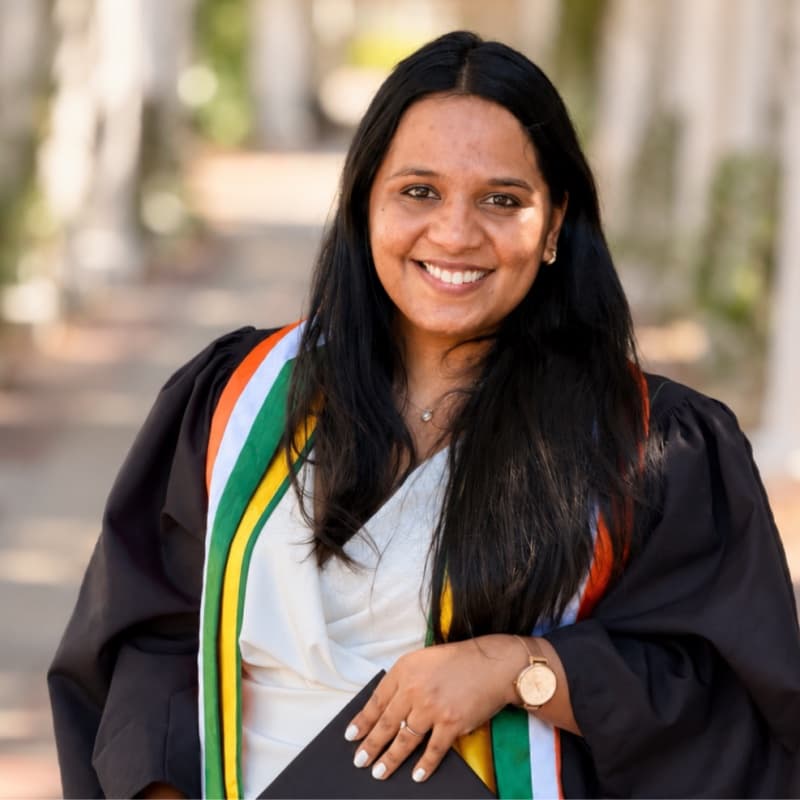
Pooja Jain
Co-founder & CEO
Trains and refines LLMs across finance domains at micro1 — the exact kind of domain-expert data work Datatation sells, not something she's read about. Before that, seven years inside institutional finance at Northern Trust Asset Management and Acuity Analytics (formerly Moody's Analytics), running investment analysis, fund reporting, and due diligence for institutional clients. MS in Financial Analytics, University of South Florida.
LinkedIn
Vichitravir Dwivedi
Co-founder & COO
Seven years building the production ML systems Datatation's clients are trying to ship — most recently leading LLM and RAG platforms at UH Systems, where part of the job was catching data drift and quality problems before they broke downstream models. He's been the engineer waiting on a data team that was a step behind. MS in Data Science, University of Texas at Dallas.
LinkedInContact
Tell us what you're building
Share the task and rough volume. We'll come back within one business day with a scoping call or a straight answer on whether we're a fit.
Prefer email? hello@datatation.com